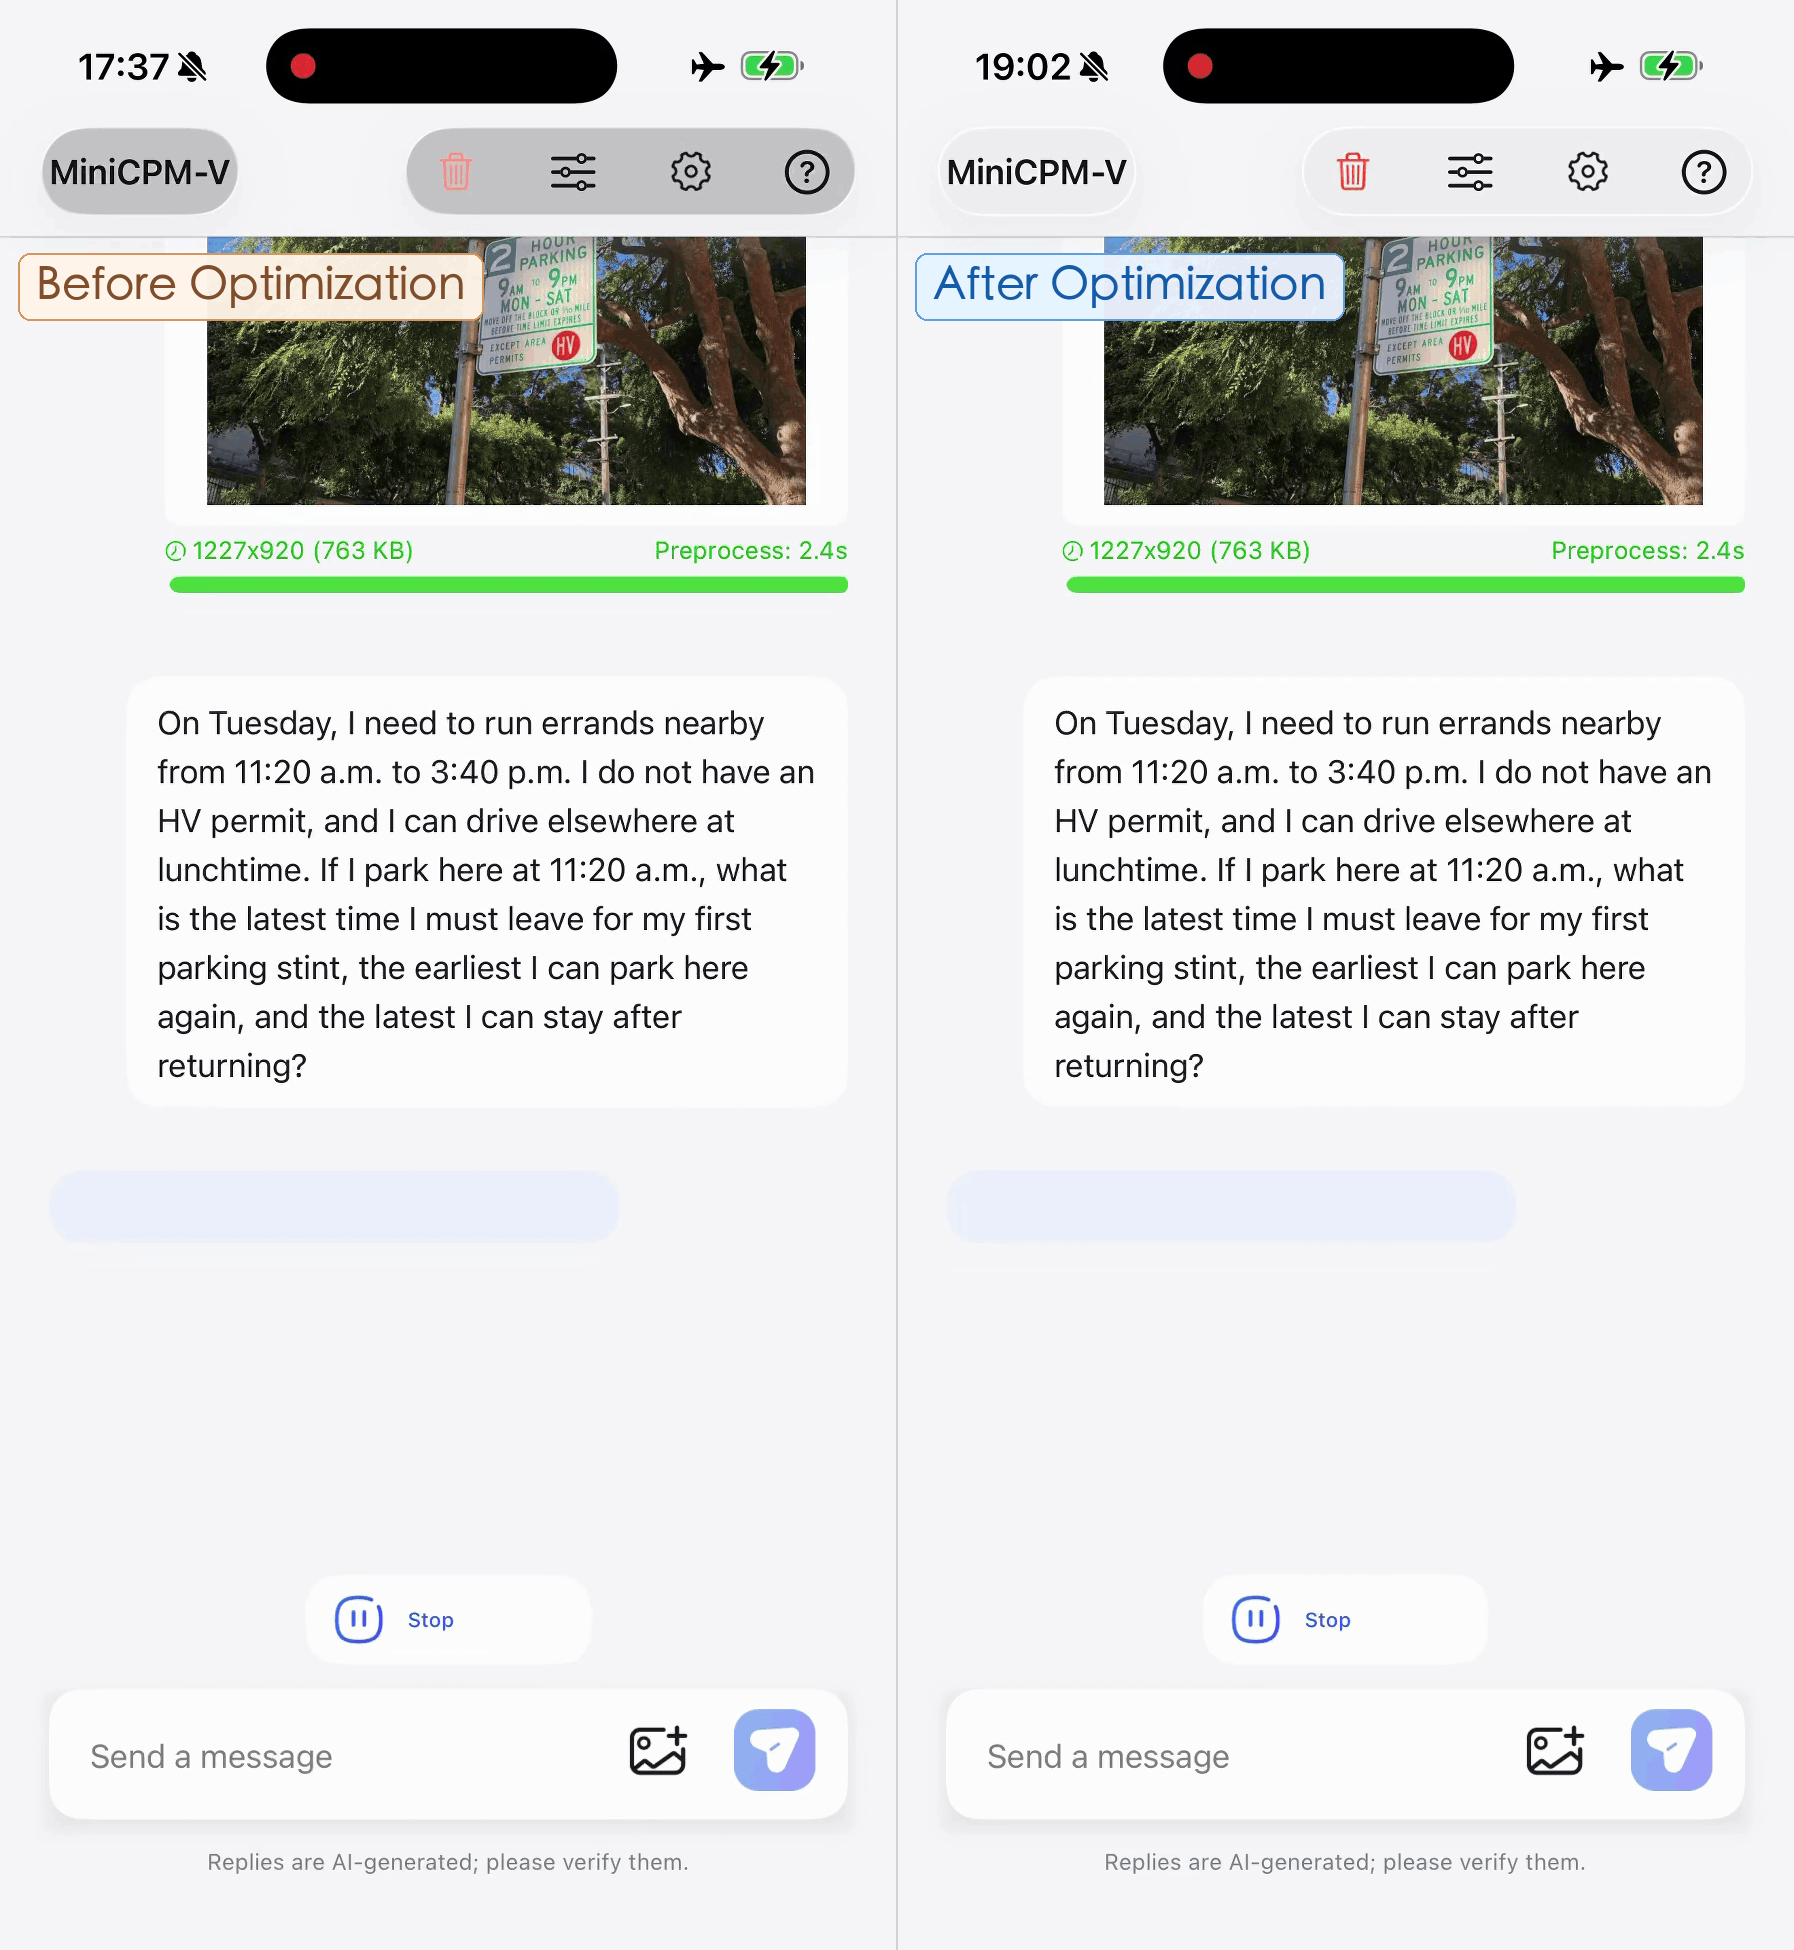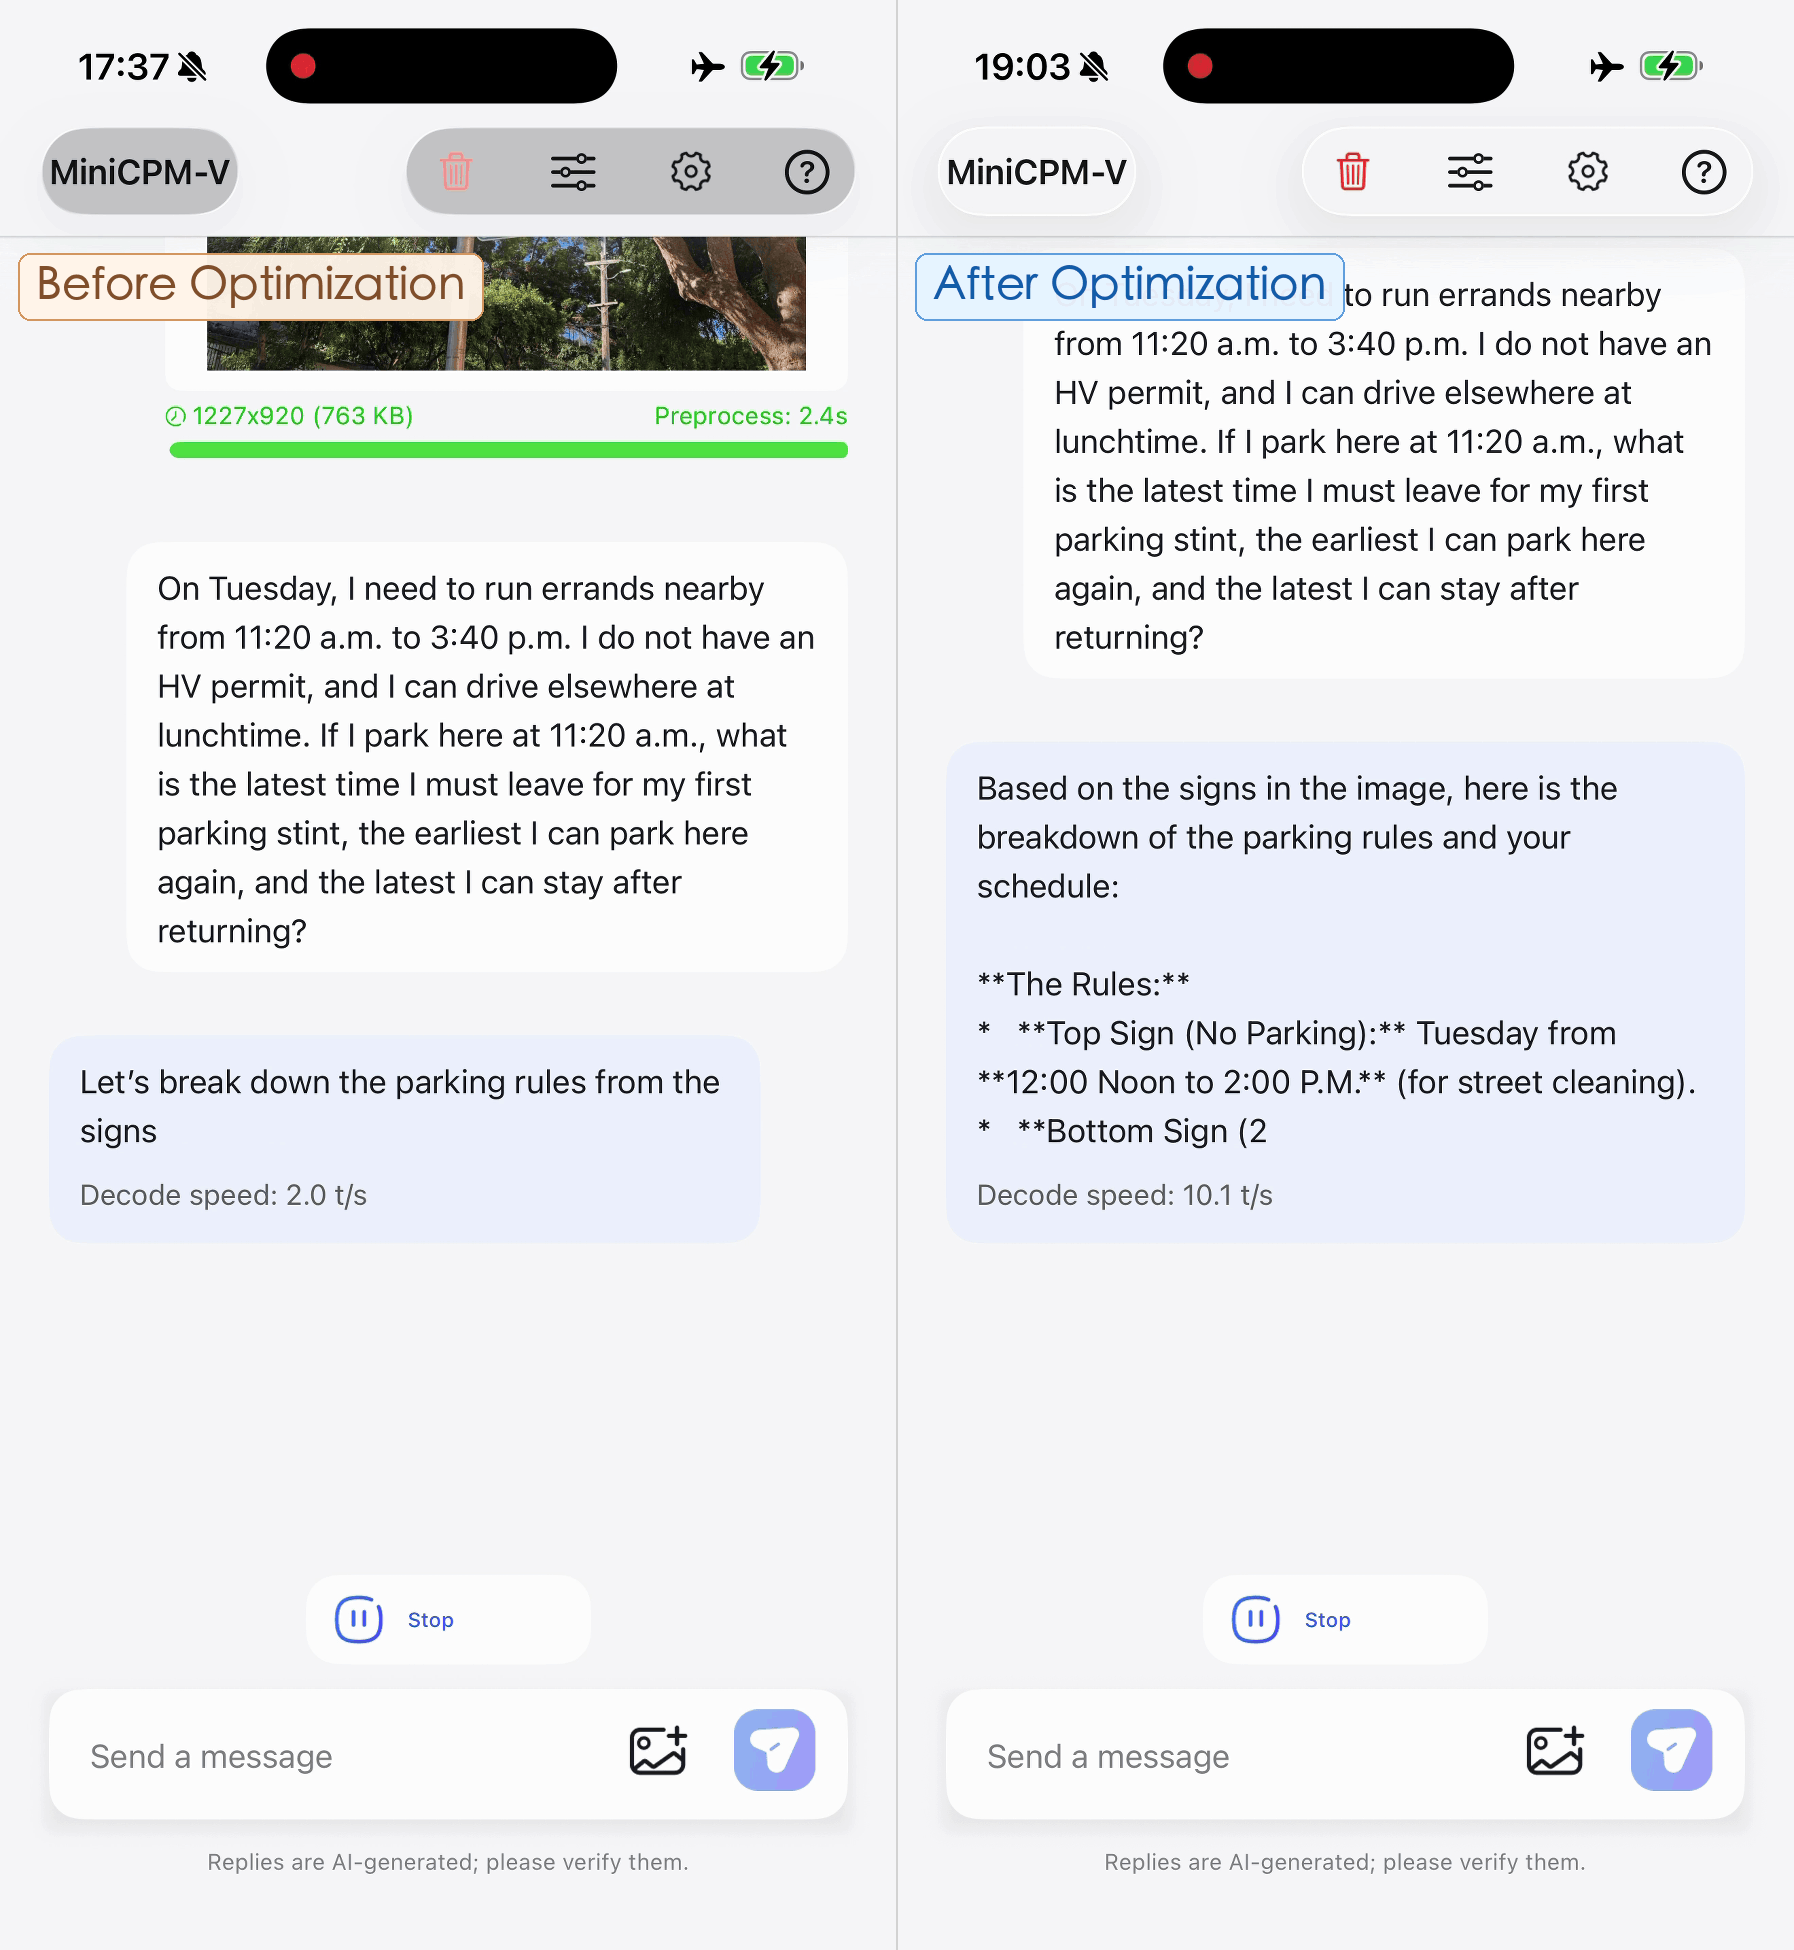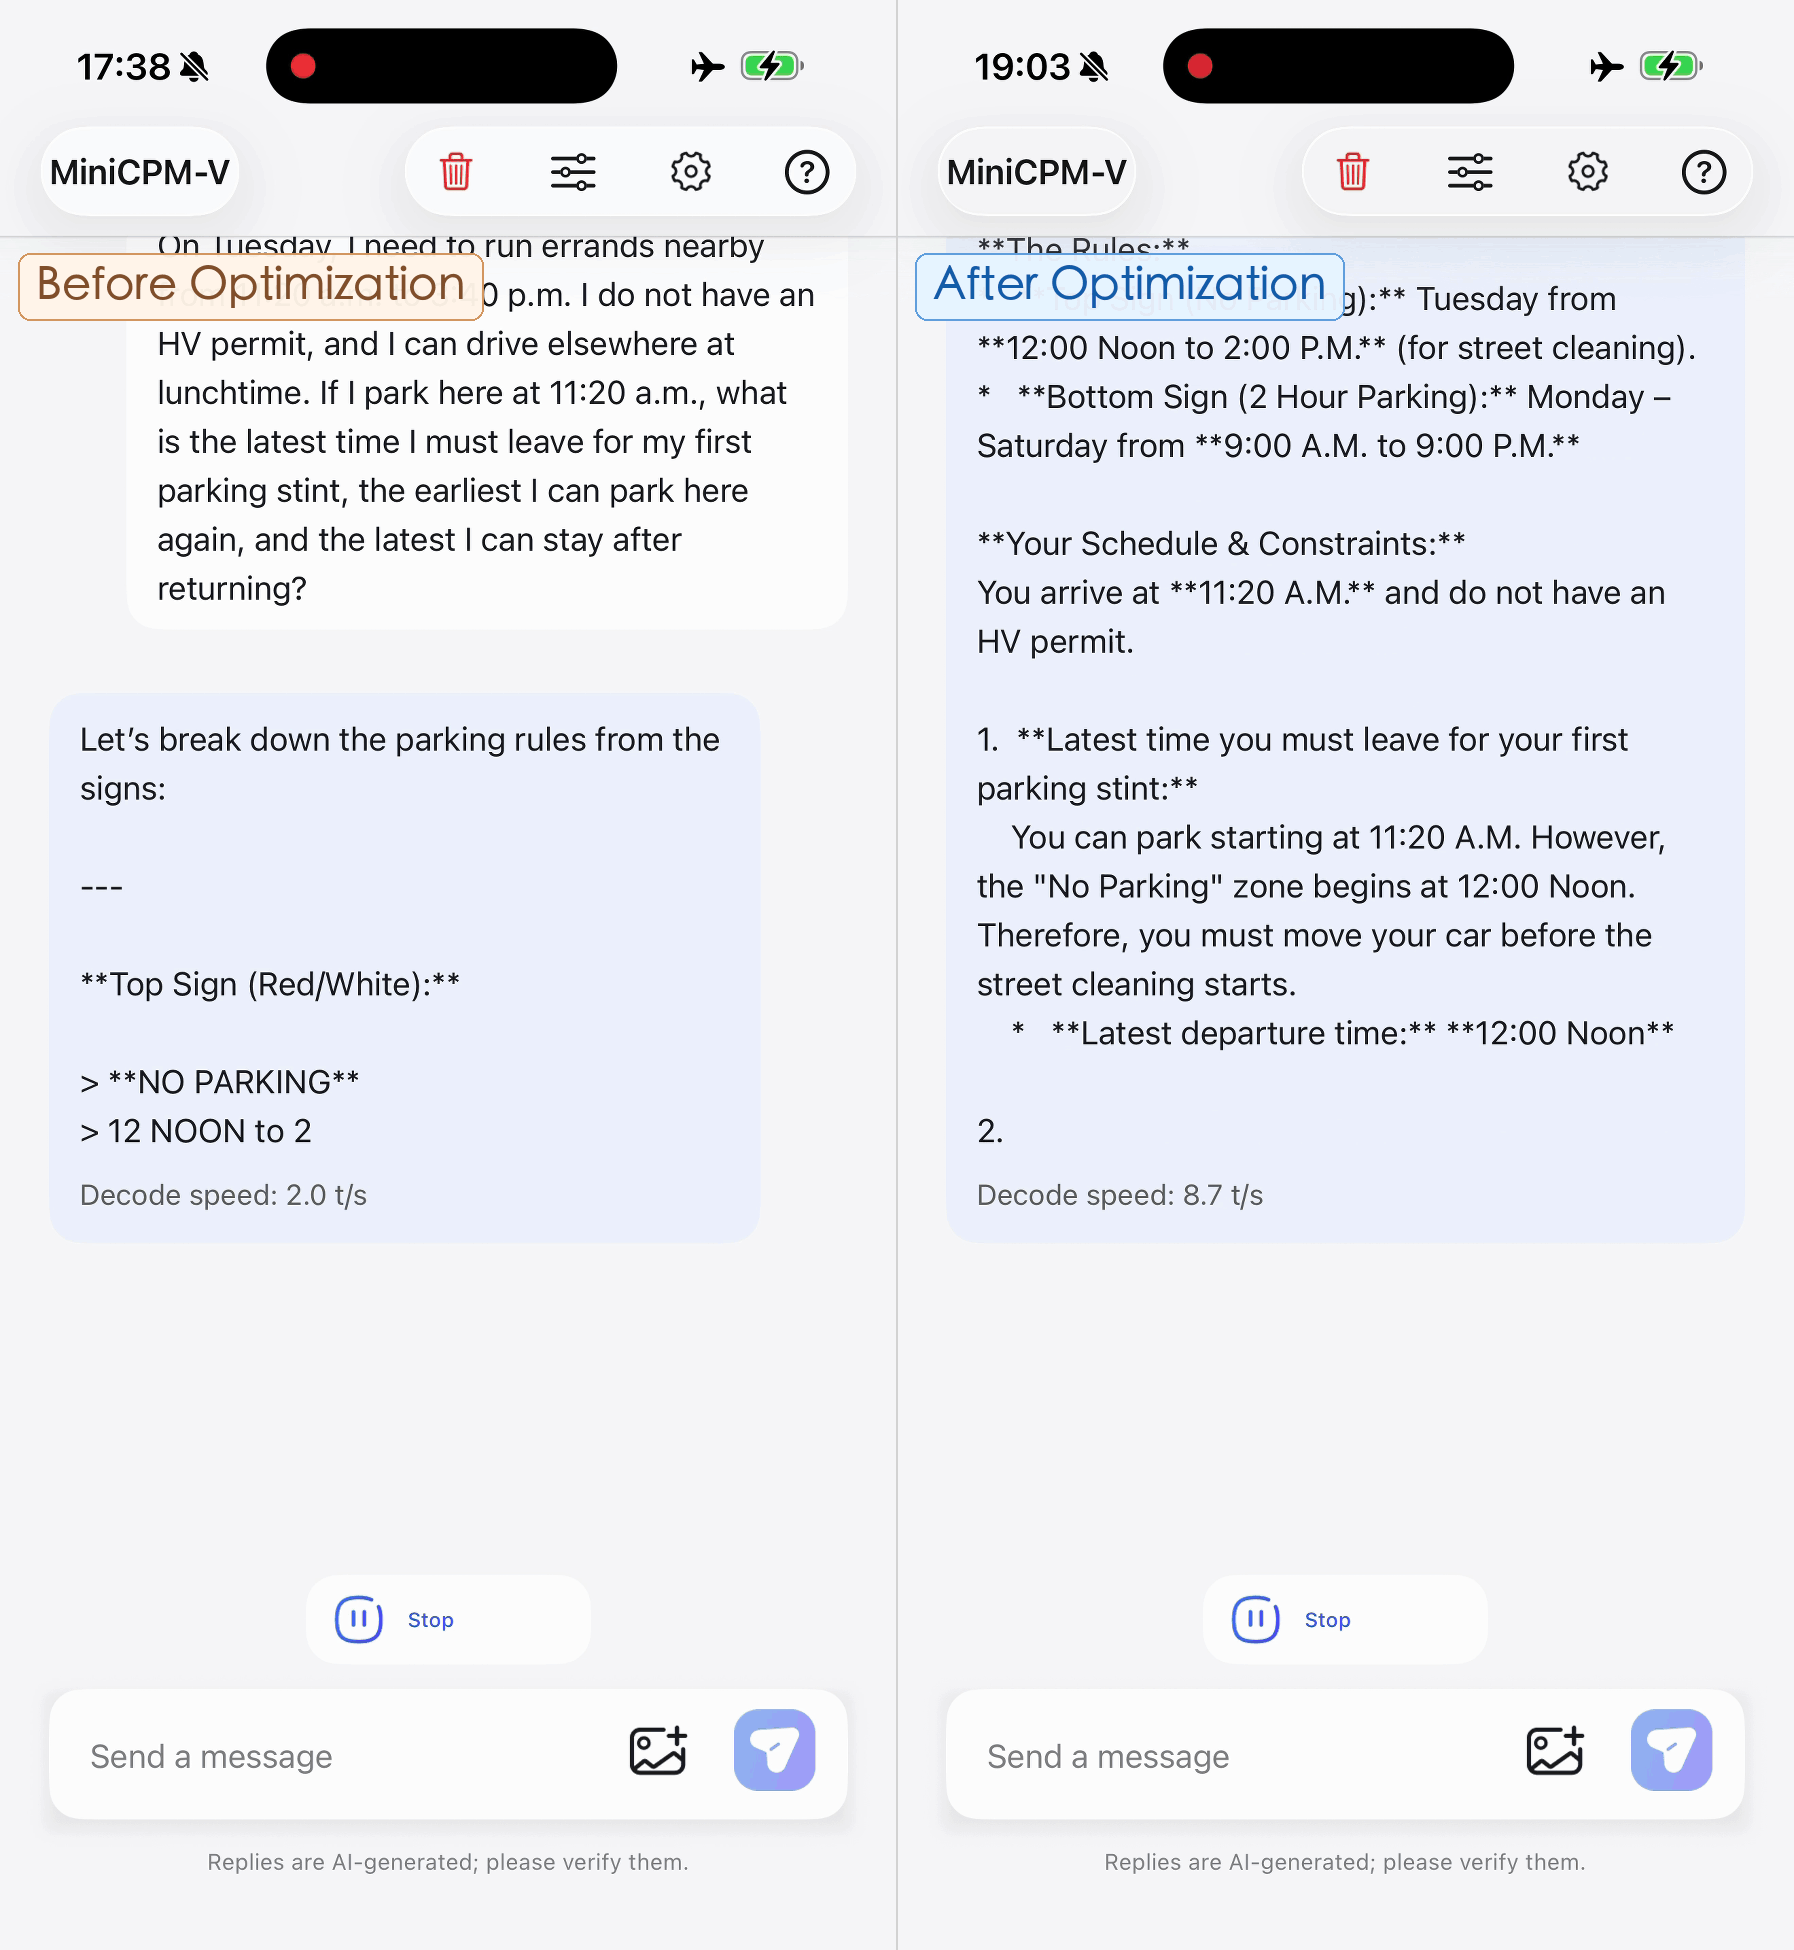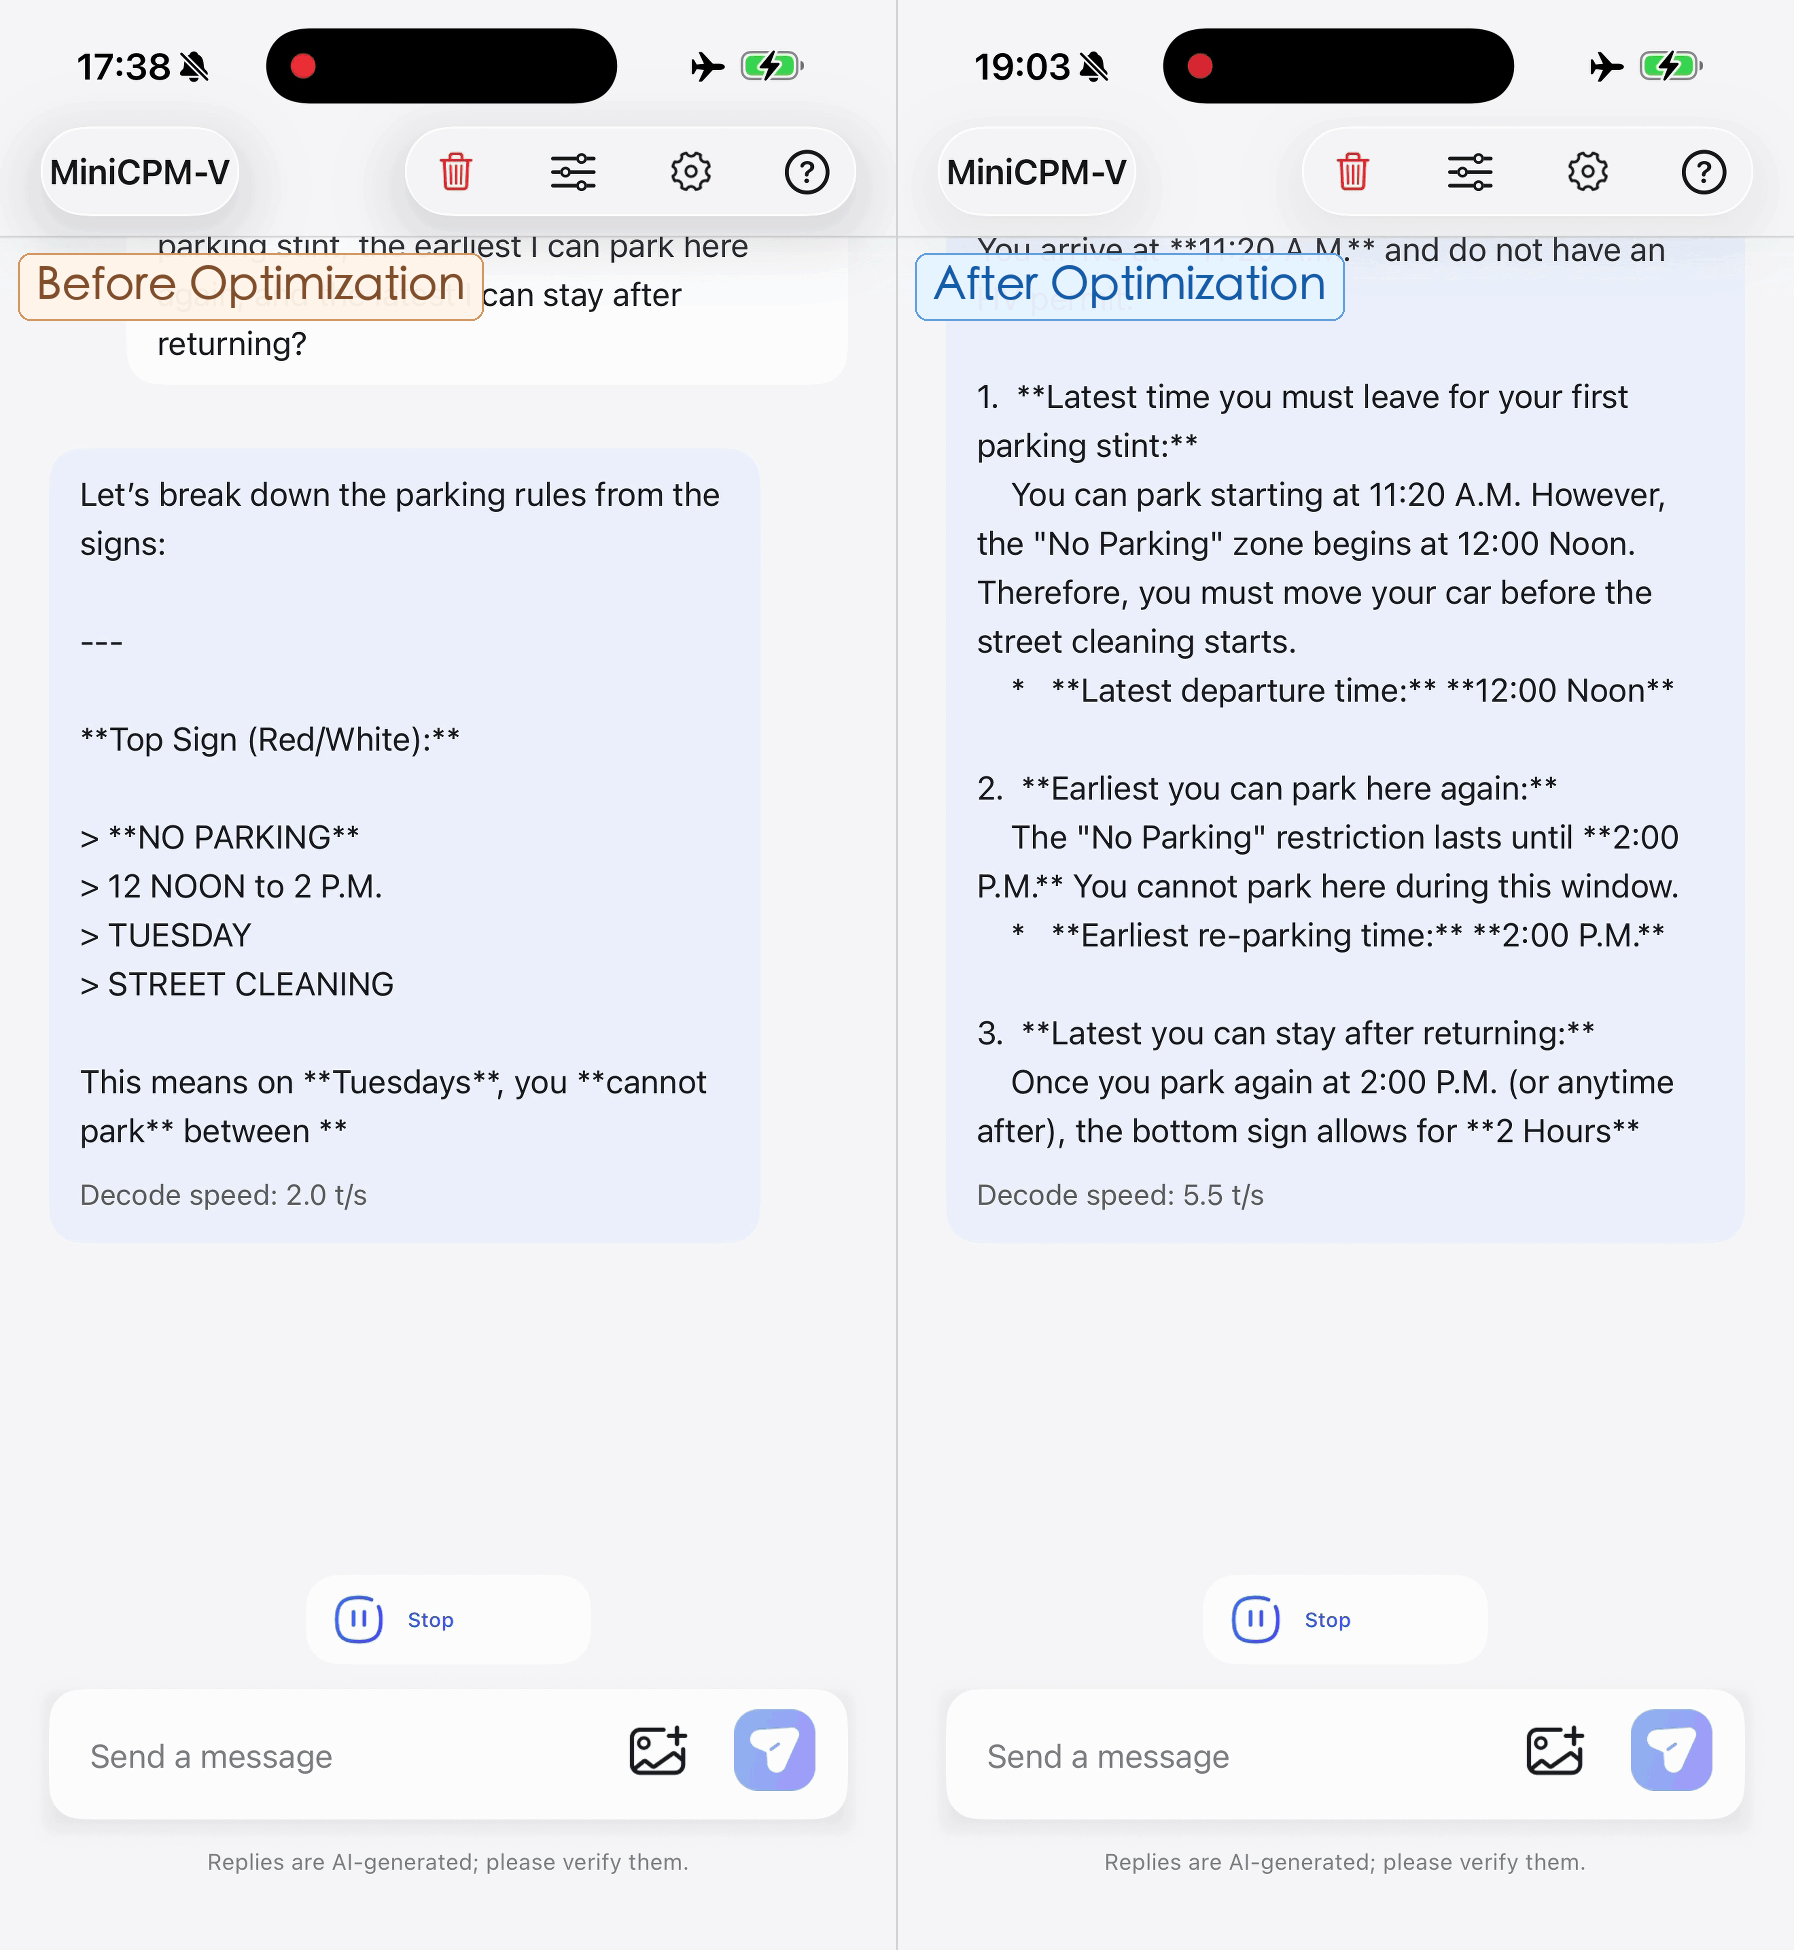
Picture published by the creator on Hugging Face.
MiniCPM-V-4.7-35B-A3B: Ask about images and video on phones
Added · Updated

Made by OpenBMB
View profile on Hugging Face (opens in a new tab)Ask questions about one image, several images or a video and get text answers.
For developers who want image and video understanding on phones and local devices.
Model details
Original model openbmb/MiniCPM-V-4.7-35B-A3B
Input Image or text Output Text
Ways to use it Browser demo · Run locally · Use through an API
One reviewed local configuration. Add My computer details to compare them.
BF16 vLLM on NVIDIA · vLLM · The pinned card lists vLLM as an inference framework and provides its Transformers inference examples. This estimate uses the BF16 checkpoint and a 4K comparison context.
How this configuration was checked
96 GB VRAM · reviewed estimate Source lists 70.4 GB (file-size). Estimate uses 70.43 GB exact BF16 checkpoint bytes, 0.084 GB 4K KV cache (10 full-attention layers of 40 hybrid layers × 2 KV heads × 256 head width × K/V × 2-byte values), 4 GB runtime buffers, and 21.486 GB remaining in the 96 GB VRAM tier.
BF16 · 4,096 token context · source context 262,144 tokens · batch size 1 · concurrency 1 · Single-user 4K comparison on the source vLLM path; the model also accepts visual inputs.
Source checked 2026-10-21 · revision 896c2d454672476a7b45dcc5e3f0c700a0218577. pinned card lists vLLM and BF16 Transformers inference; exact checkpoint shard bytes and hybrid attention config supply the estimate inputs
What it does
MiniCPM-V 4.7 is a multimodal model, meaning an AI that understands more than text. The source says it builds on the family's single-image, multi-image and video understanding. This variant is a mixture-of-experts model, where only part of the model is used for each piece of text. The creators say it compresses visual information early inside its vision encoder, which reduces computing, and that developers can choose a mixed 4x/16x compression to trade visual detail against cost.
How to use it
Input → action → output: give it an image, several images or a video plus your question, run it, and read the model's answer. Get the weights from Hugging Face and run them with a framework the source lists: SGLang, vLLM, llama.cpp or Ollama. The page also lists compressed (quantized) versions in GGUF, BNB, AWQ and GPTQ formats, and a live demo link under Get started.
Common use cases
- Show the model one image and ask what is in it.
- Give it several images together and ask a question about them.
- Give it a video and ask it to answer questions about what happens.
Can I use this?
Requirements The model is open source under Apache 2.0 and not gated, so no access request is needed. Download the weights from the model page and use a supported framework. The creators say it supports iOS, Android and HarmonyOS. Exact RAM or GPU needs for the full model are not documented.
Caveat The creators report decoding at 13+ tokens per second with 3 GB of memory on an iPhone 17 Pro Max, using their own llama.cpp-omni technique and quantization. That is their claim for one device. The source also notes that mixture-of-experts storage needs are not limited to the active parameters.
Worth knowing The speed figure is the creators' claim for one iPhone; results on other devices are not documented. Licensed under Apache License 2.0.
Why it's here
Not trending this week
Last seen on the Hugging Face trending list on 19 October 2026. It stays on BuildTube so you can still find it.
- 1,115 people have liked it on Hugging Face.
- It was downloaded 637,750 times in the last 30 days.
Numbers checked on 8 November 2026; not refreshed since.
Behind it
View model pageBuildTube has not run or verified this project. Everything above is written from what the creator published.
Made this?
Quick questions
- What is MiniCPM-V-4.7-35B-A3B?
- MiniCPM-V 4.7 is a multimodal model, meaning an AI that understands more than text.
- What can I use MiniCPM-V-4.7-35B-A3B for?
- Show the model one image and ask what is in it; Give it several images together and ask a question about them; Give it a video and ask it to answer questions about what happens
- Can I run MiniCPM-V-4.7-35B-A3B on my computer?
- It runs on your own hardware with a model runtime. The creators say it supports iOS, Android and HarmonyOS. Exact RAM or GPU needs for the full model are not documented.
- What do I need to use MiniCPM-V-4.7-35B-A3B?
- Open source under Apache 2.0 and not gated. Needs a supported framework such as SGLang, vLLM, llama.cpp or Ollama.
- What license does MiniCPM-V-4.7-35B-A3B use?
- Licensed under Apache License 2.0.
More from this week
- kimi-k3-in-c Run a 2.78-trillion-parameter model on 8 GB of RAM
Get text answers from the huge Kimi K3 AI model using one CPU and no graphics card.
- Idol Turn one picture of an object into a 3D Gaussian splat
Idol turns one photo, render or generated image of an object into a 3D Gaussian splat file.
- P-H3-Image-Comfy Make and edit 8-megapixel images in ComfyUI
Turn short text requests into 8-megapixel images and edit pictures on your own graphics card.
Explore by topic
Post this
 Download share image
For makers
Made this? Show it’s on BuildTube — add the badge to your README or embed the card on your site.
README badge (Markdown)
[](https://buildtube.app/p/hf-openbmb-minicpm-v-4-7-35b-a3b/)Embed card (HTML)
<iframe src="https://buildtube.app/embed/hf-openbmb-minicpm-v-4-7-35b-a3b/" width="560" height="240" style="border:0;max-width:100%" loading="lazy" title="MiniCPM-V-4.7-35B-A3B on BuildTube"></iframe>